
Artificial Analysis posted at 19:45 UTC on 9 November 2026, which is 03:45 in Beijing on 10 November. The post says Anthropic has released Claude Fable 5.2 and that the model takes first place on the Artificial Analysis Intelligence Index v5 with a score of 65. The post attributes the gain to scientific reasoning, knowledge, and FrontierCode 2.0.
[1]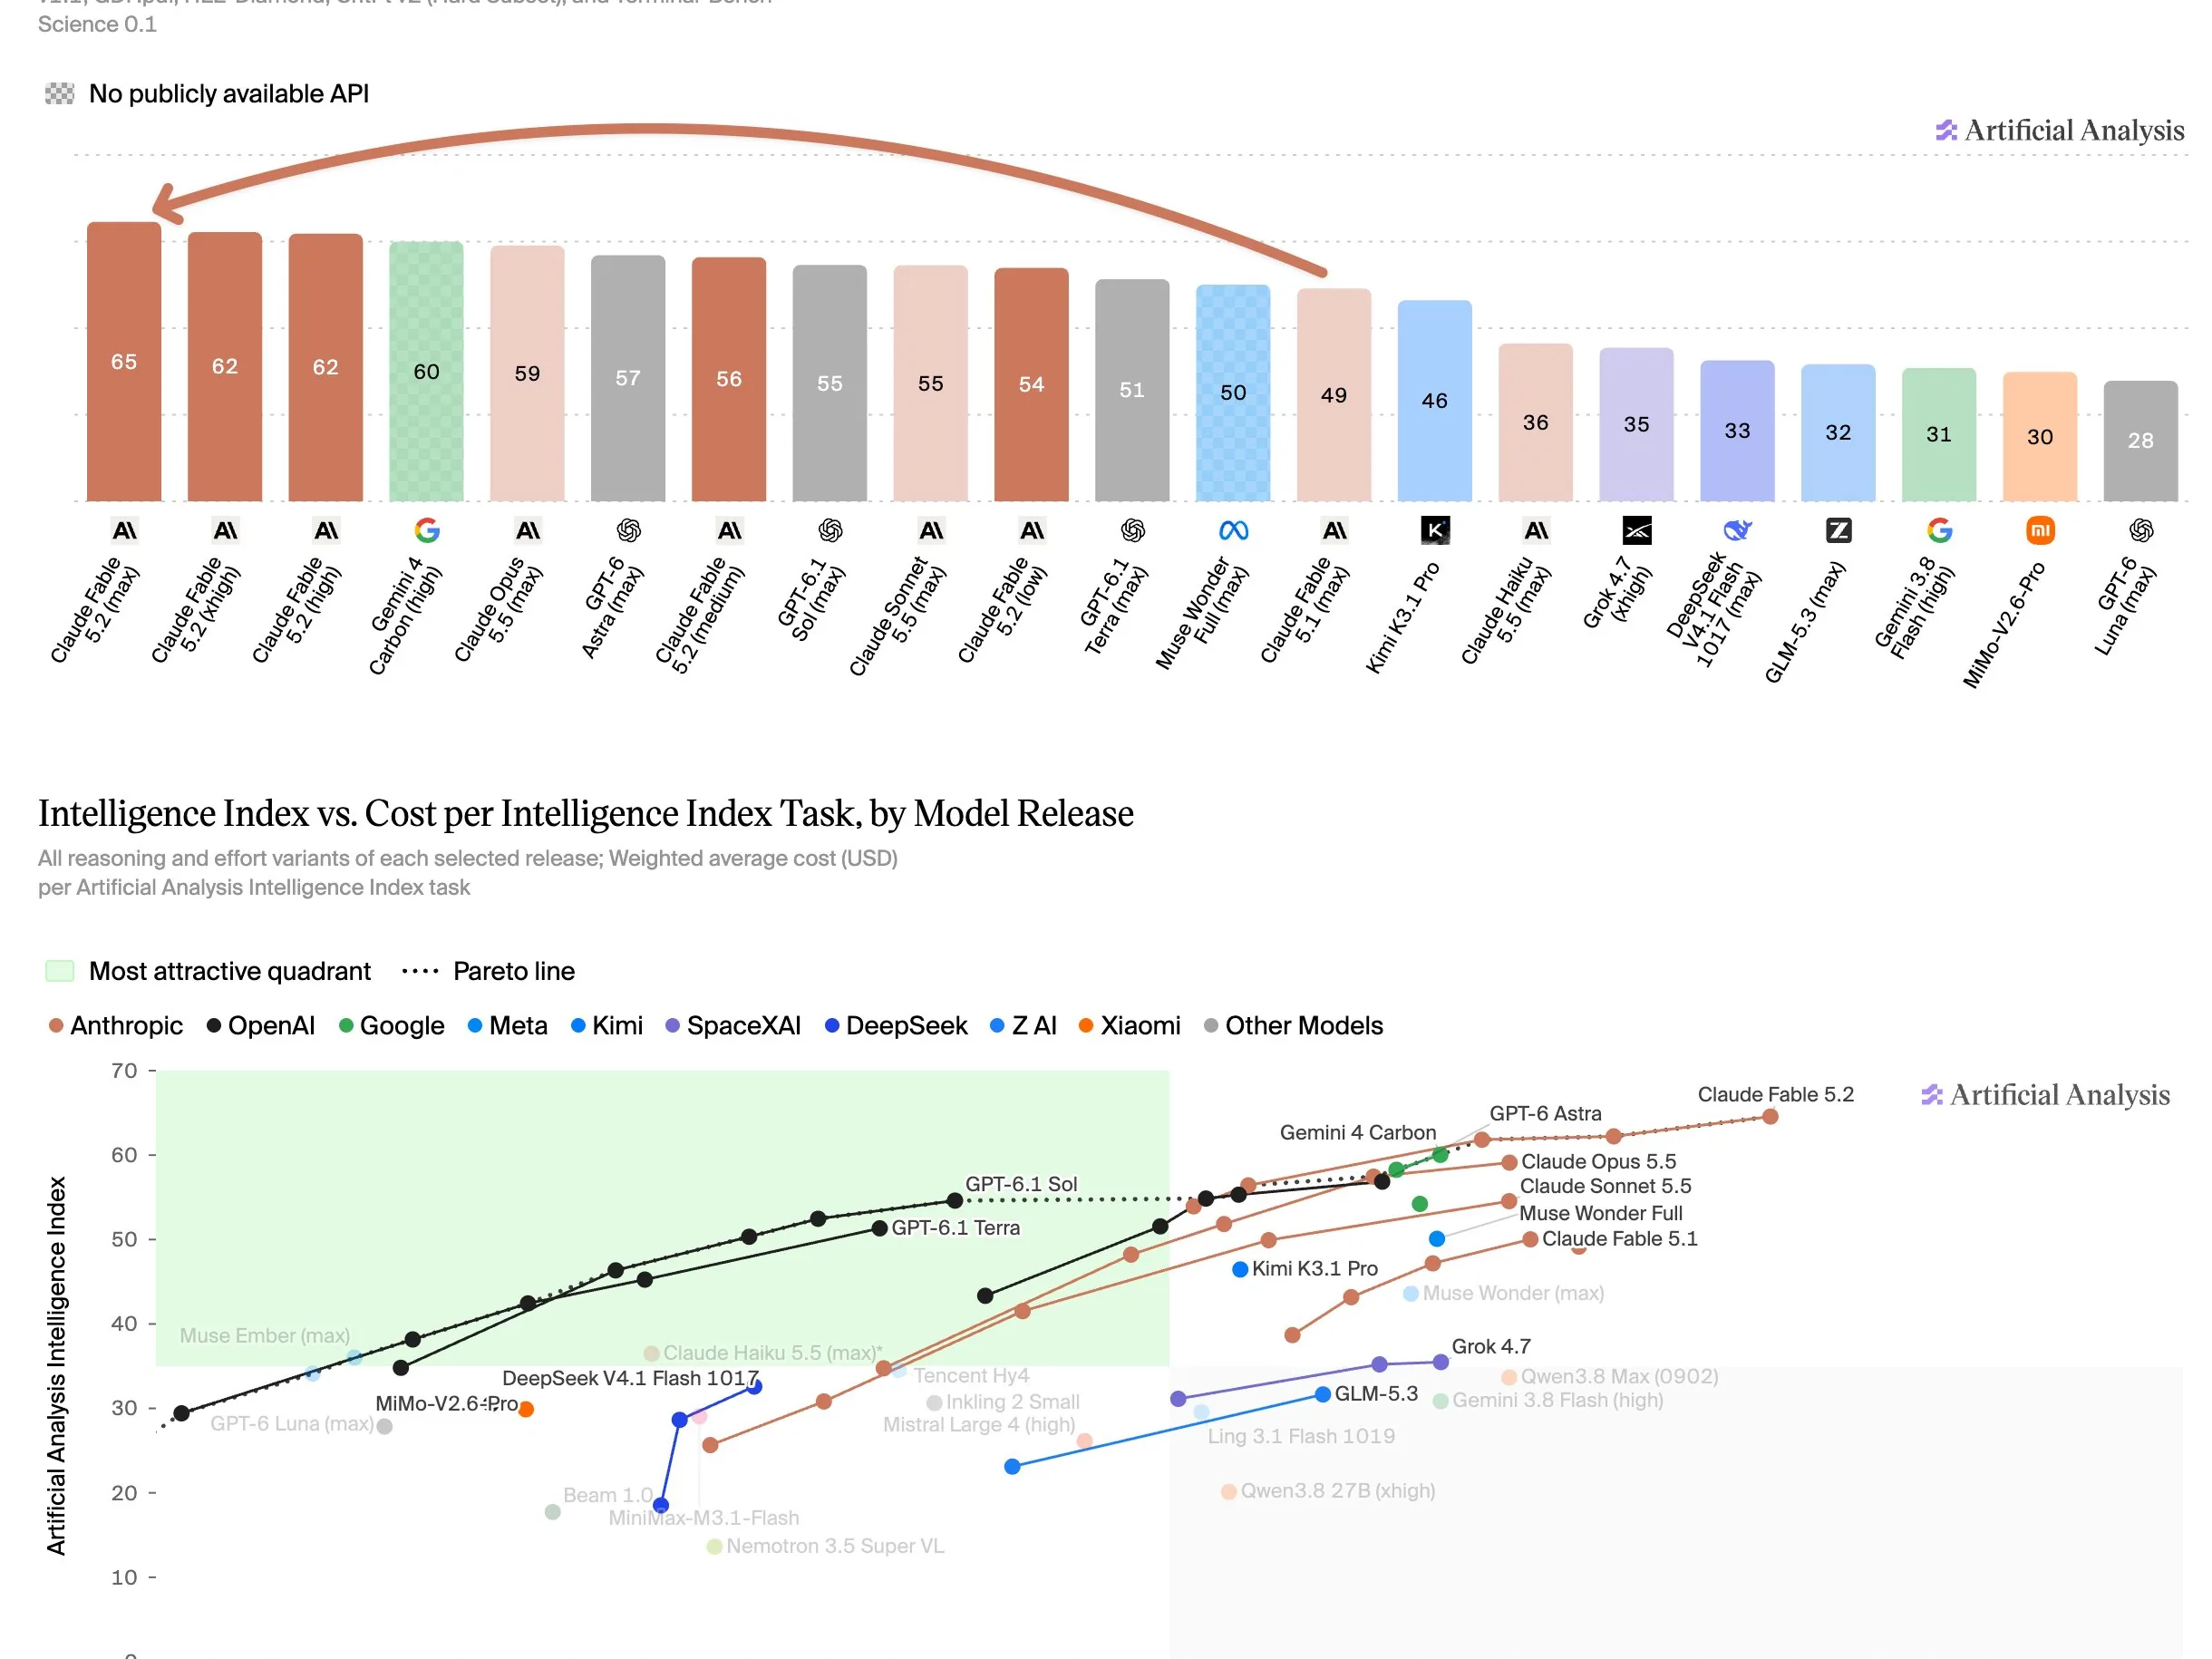
At maximum effort the score is 65, five points above Gemini 4 Carbon at high effort (60) and six points above Claude Opus 5.5 at maximum effort (59). It is also above GPT-6 Astra at maximum effort (57) and about 15 points above Claude Fable 5.1 at maximum effort (49). The post says Fable 5.2 leads 5 of the 9 evaluations in the index and sets the current highs on HLE-Diamond at 80 percent (previous best 69 percent, Gemini 4 Carbon), AA-Omniscience v1.1 at 67 (previous best 54, Gemini 4 Carbon), Terminal-Bench-Science at 73 percent (previous best 65 percent), the CritPt v2 hard subset at 77 percent (previous best 72 percent, GPT-6 Astra), and FrontierCode 2.0 at 49 percent (previous best 46 percent, Claude Opus 5.5).
[1]The same post lists the evaluations that did not pull away. AA-Briefcase is 1785 Elo, inside the confidence interval of Opus 5.5 at 1800 and just behind Claude Sonnet 5.5 at 1813. GDP.pdf all-pass is 24 percent, against 26 percent for Opus 5.5. Terminal-Bench 4.0 is 60 percent, level with Opus 5.5 and behind Kimi K3.1 Pro at 67 percent, Gemini 4 Carbon at 65 percent, and Sonnet 5.5 at 64 percent. AutomationBench-AA is the exception, at 76 percent against 70 percent for Opus 5.5 and still narrowly behind Gemini 4 Carbon at 78 percent.
[1]The listed price is 8 dollars per million input tokens and 40 dollars per million output tokens, a 20 percent reduction from Fable 5.1. Cost per task at maximum effort is 26.5 dollars, about 2.6 times the 10.0 dollars listed for Opus 5.5 at maximum effort and about twice the 12.99 dollars listed for Fable 5.1 at maximum effort. High and extra-high effort score 62. The post says that is ahead of every other model at any effort, with about 98,000 output tokens per task against 173,000 for Opus 5.5 at maximum effort. It also says lower effort settings can beat Opus 5.5 at a lower cost per task. The context window is 1 million tokens, with image and text input. Cache writes are listed at 10 dollars per million for a five-minute TTL and 16 dollars for a one-hour TTL, and cache reads at 0.20 dollars. There are five effort settings, and the index was run at all five with Anthropic's default fallback enabled.
[1]The post does not say whether the scores were reproduced independently, and it does not separate a general release from a preview. Anthropic's announcement page carries only the date 9 November and no clock, so this column uses the timed evaluation post and does not fold in other claims from that page.
[1]要点
- Index v5 at maximum effort is 65, with five of nine evaluations called current highs
- Document and terminal evaluations mostly sit near Opus 5.5
- Maximum-effort cost per task is 26.5 dollars, about 2.6 times Opus 5.5