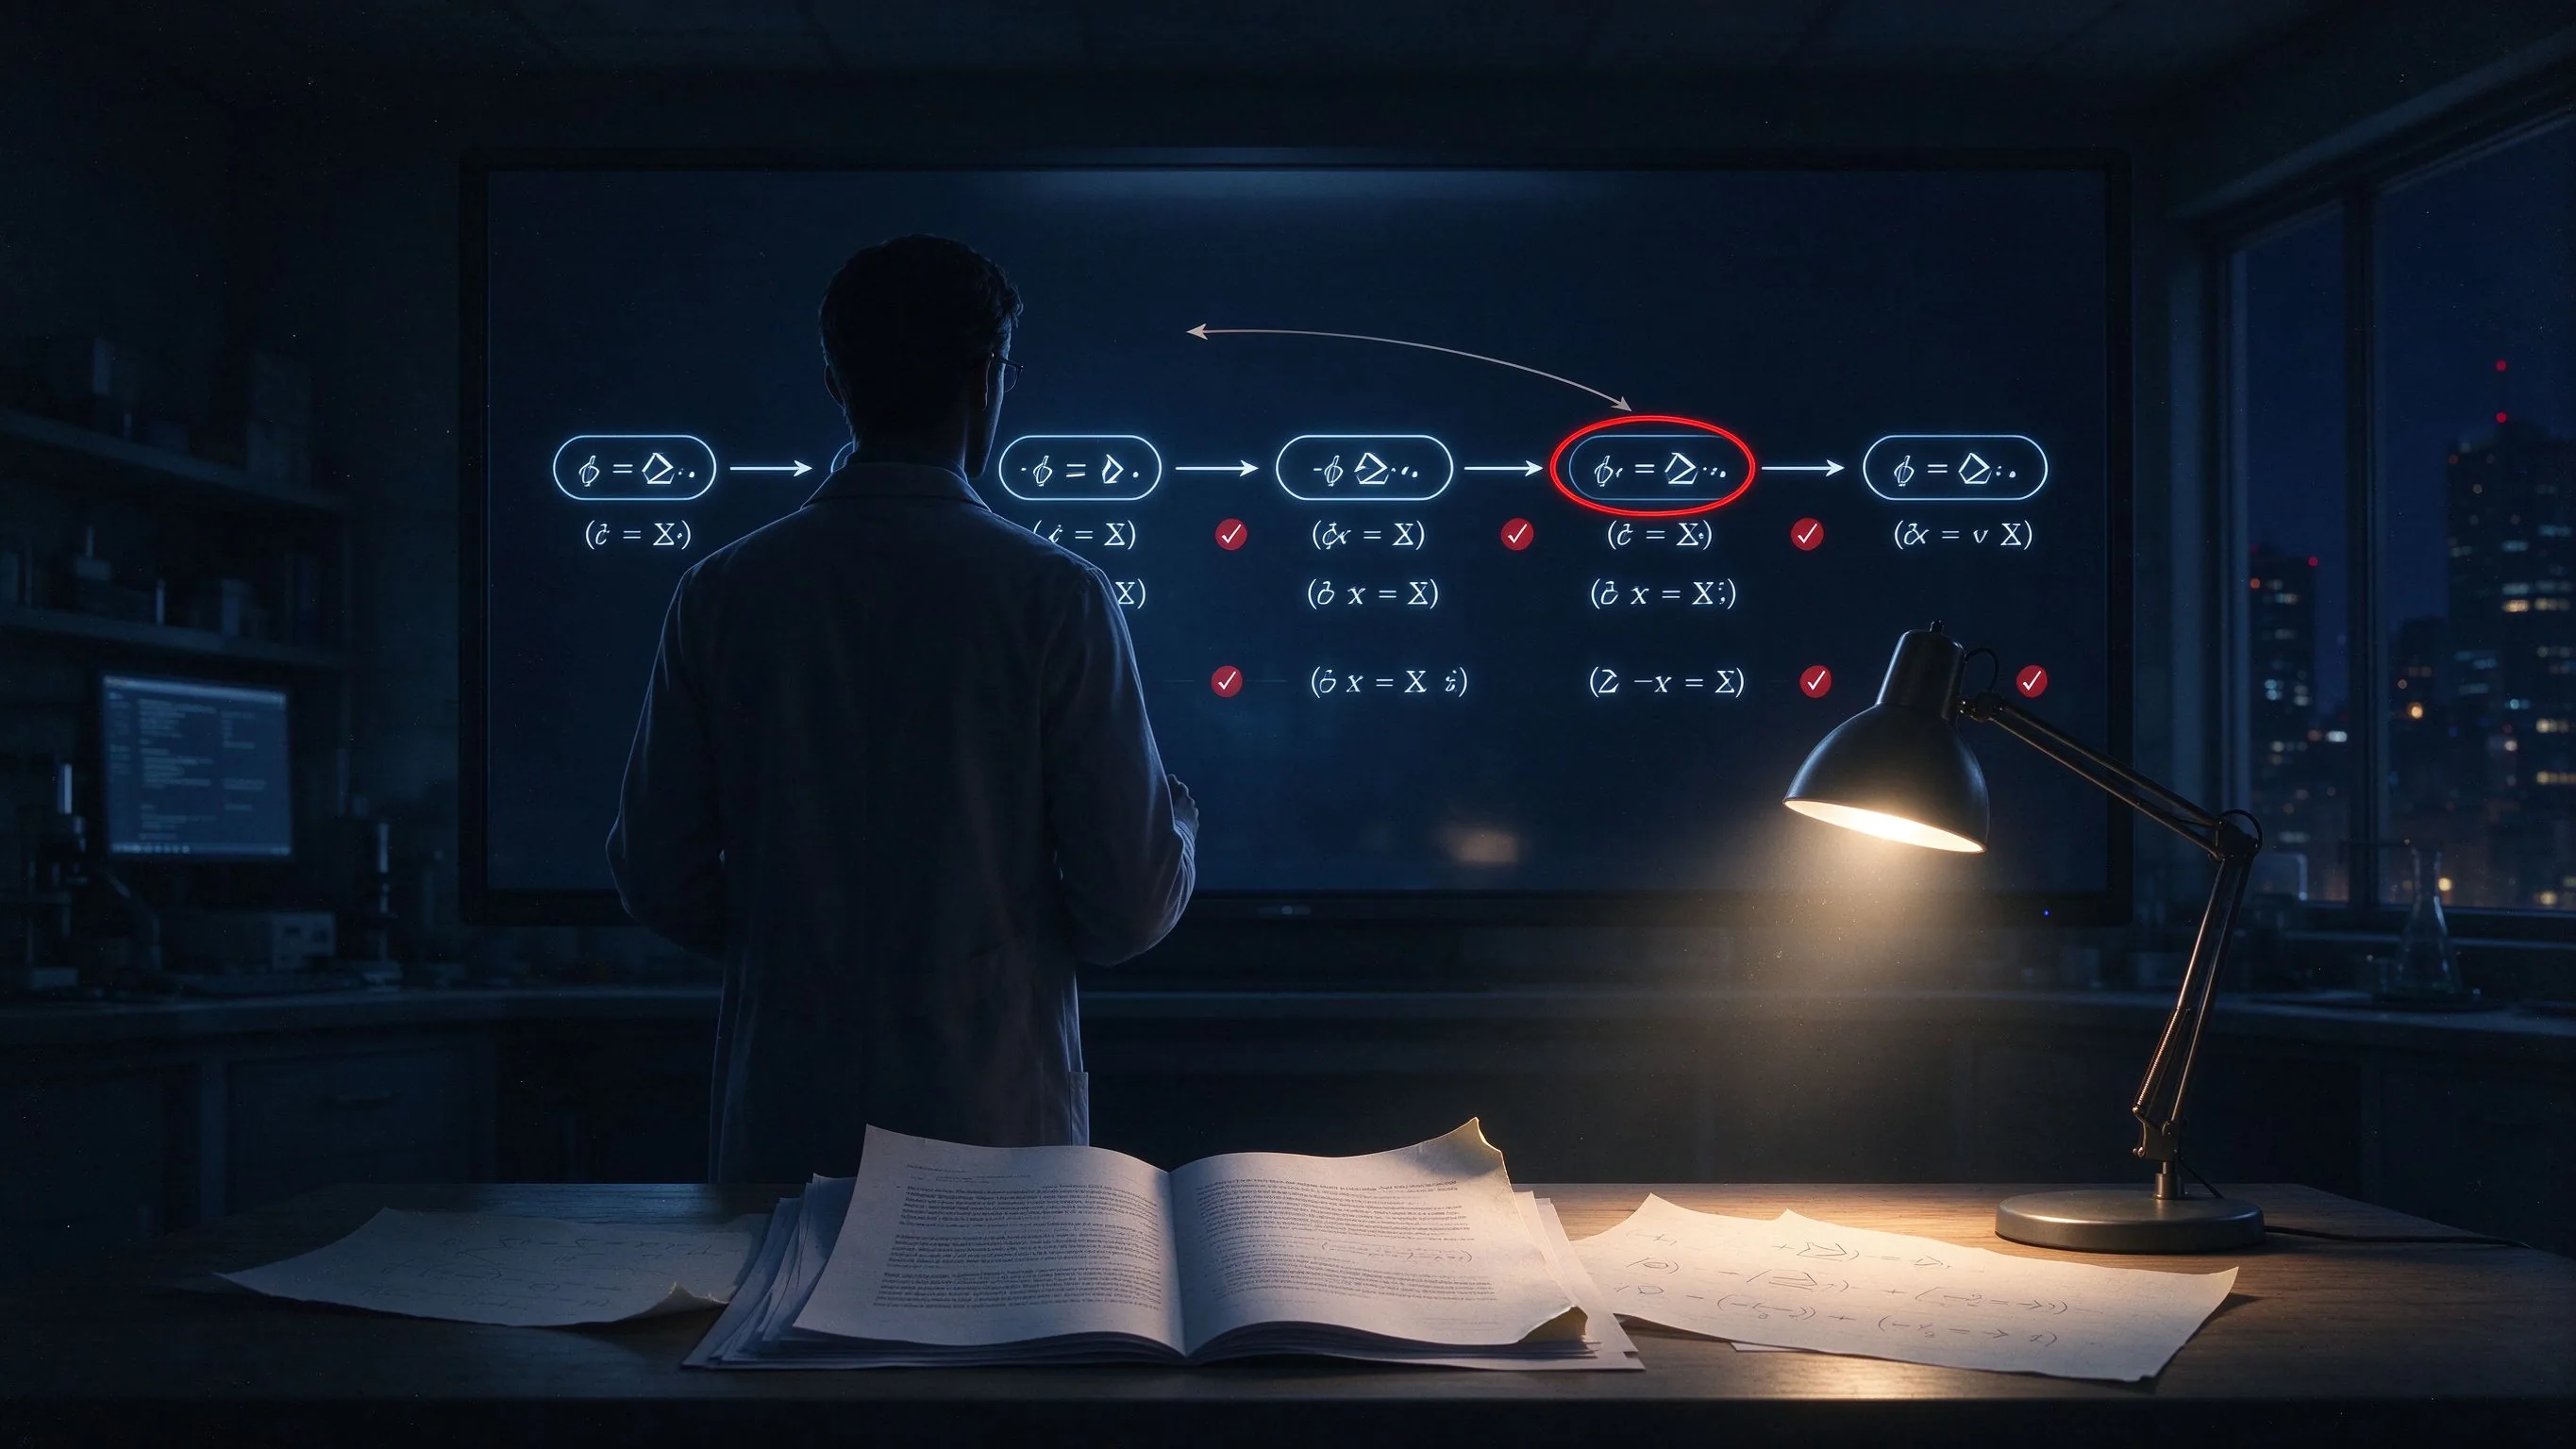
A paper posted to arXiv on September 18 (arXiv:2609.21492, LogicTrack) targets a blind spot in chain-of-thought reasoning: existing optimization largely looks only at whether the final answer is correct, while a model can perfectly well produce a correct answer through a logically broken chain. LogicTrack auto-formalizes each natural-language reasoning step into symbolic form, verifies it step by step with automated theorem provers, and uses solver-based scoring to guide backtracking search at inference time — across 8 reasoning benchmarks and 7 LLMs, both intermediate-step validity and final-answer pass rate improve.
[1][2]First, what problem it solves. CoT gets models to write their thinking down, but nearly all training and evaluation is outcome-based: reward the right answer, never check the intermediate lines. The result is that a model can reach the right answer by memorization, pattern matching, or sheer luck, with the "reasoning" in between being logically invalid. In high-stakes settings — medicine, finance, autonomous decision-making — "right answer, wrong process" is harder to catch and more dangerous than a plain wrong answer, because no human can line-by-line audit every chain. LogicTrack's idea is to attach an auditor to the reasoning process itself: translate each step into formal logic and let a theorem prover check whether this step actually follows from the previous ones.
The mechanism has two layers. At inference time, the Solver-Based Backtracking Reward (SBR) scores each step by quantifying logical soundness and guides a backtracking tree search — when a step fails to derive, the model backtracks and retries instead of running all the way to a wrong answer. On the training side, the authors construct supervised fine-tuning data from backtracking traces, letting a fine-tuned model internalize step-wise auditing as a capability rather than depending on an external solver every time. Experiments across 8 benchmarks and 7 LLMs show final-answer pass rate and reasoning-chain verifiability improving together, with ablations and search-strategy variants supporting generality. The neuro-symbolic combo is not new — Logic-LM and Certified Deductive Reasoning are predecessors — LogicTrack's increment is upgrading verification from post-hoc checking to a reward signal inside the reasoning process itself.
Limits must be stated. Auto-formalization can fail or distort; translating messy natural-language steps into symbols loses information. The reported gains are relative to baselines (common CoT, self-consistency, and similar), and the abstract does not give per-benchmark numbers for all eight. Backtracking search adds compute at inference time, and the cost on long chains is not quantified in the abstract. The authors do not claim to fix the higher-order failure of "formalized correctly but the question was misread." Overall it fills the process-audit slot — a new tool in the trustworthy-reasoning toolbox, not the end of reasoning correctness.
Why this direction is gathering momentum is worth a paragraph. The field's verification stack has matured quickly — Lean and other proof assistants give deductive reasoning a machine-checkable standard, and process-supervision research has shown that step-level feedback beats outcome-only reward — yet almost all of it lives in the formal-proving corner, while the general CoT that every chatbot emits remains unaudited. LogicTrack is part of a wave trying to close exactly that gap between the formal and the conversational, and the practical payoff is concrete: an audit flag on a single wrong step, with a backtrack that fixes it, is worth more in a production agent than a slightly higher pass rate on a benchmark. The authors' choice to publish the backtracking traces as SFT data also points at a self-improvement loop — models that learn to audit their own chains without a solver at serving time. Whether that loop holds at frontier scale, and whether formalization loss stays acceptable on messy real-world reasoning, are the two questions this line of work has to answer next.
[1][2]