
On 24 October 2026, Tencent WorkBuddy added the model Kimi-K3.1-Pro. The stamp on this IT Home page is 2026/10/24 15:59:12, and the article places the integration on that day. The same paragraph says WorkBuddy also added the high-speed model, Kimi K3.1 Pro Highspeed. The high-speed model is described as having the same intelligence, with output about 2-3 times as fast. Resources are tight. For the present stage, priority access is limited to the enterprise flagship plan and personal subscribers. The picture is the model list in the article. The high-speed row is marked for subscriber priority, which matches that priority access. Figures on the other rows are not written in the article.
[1]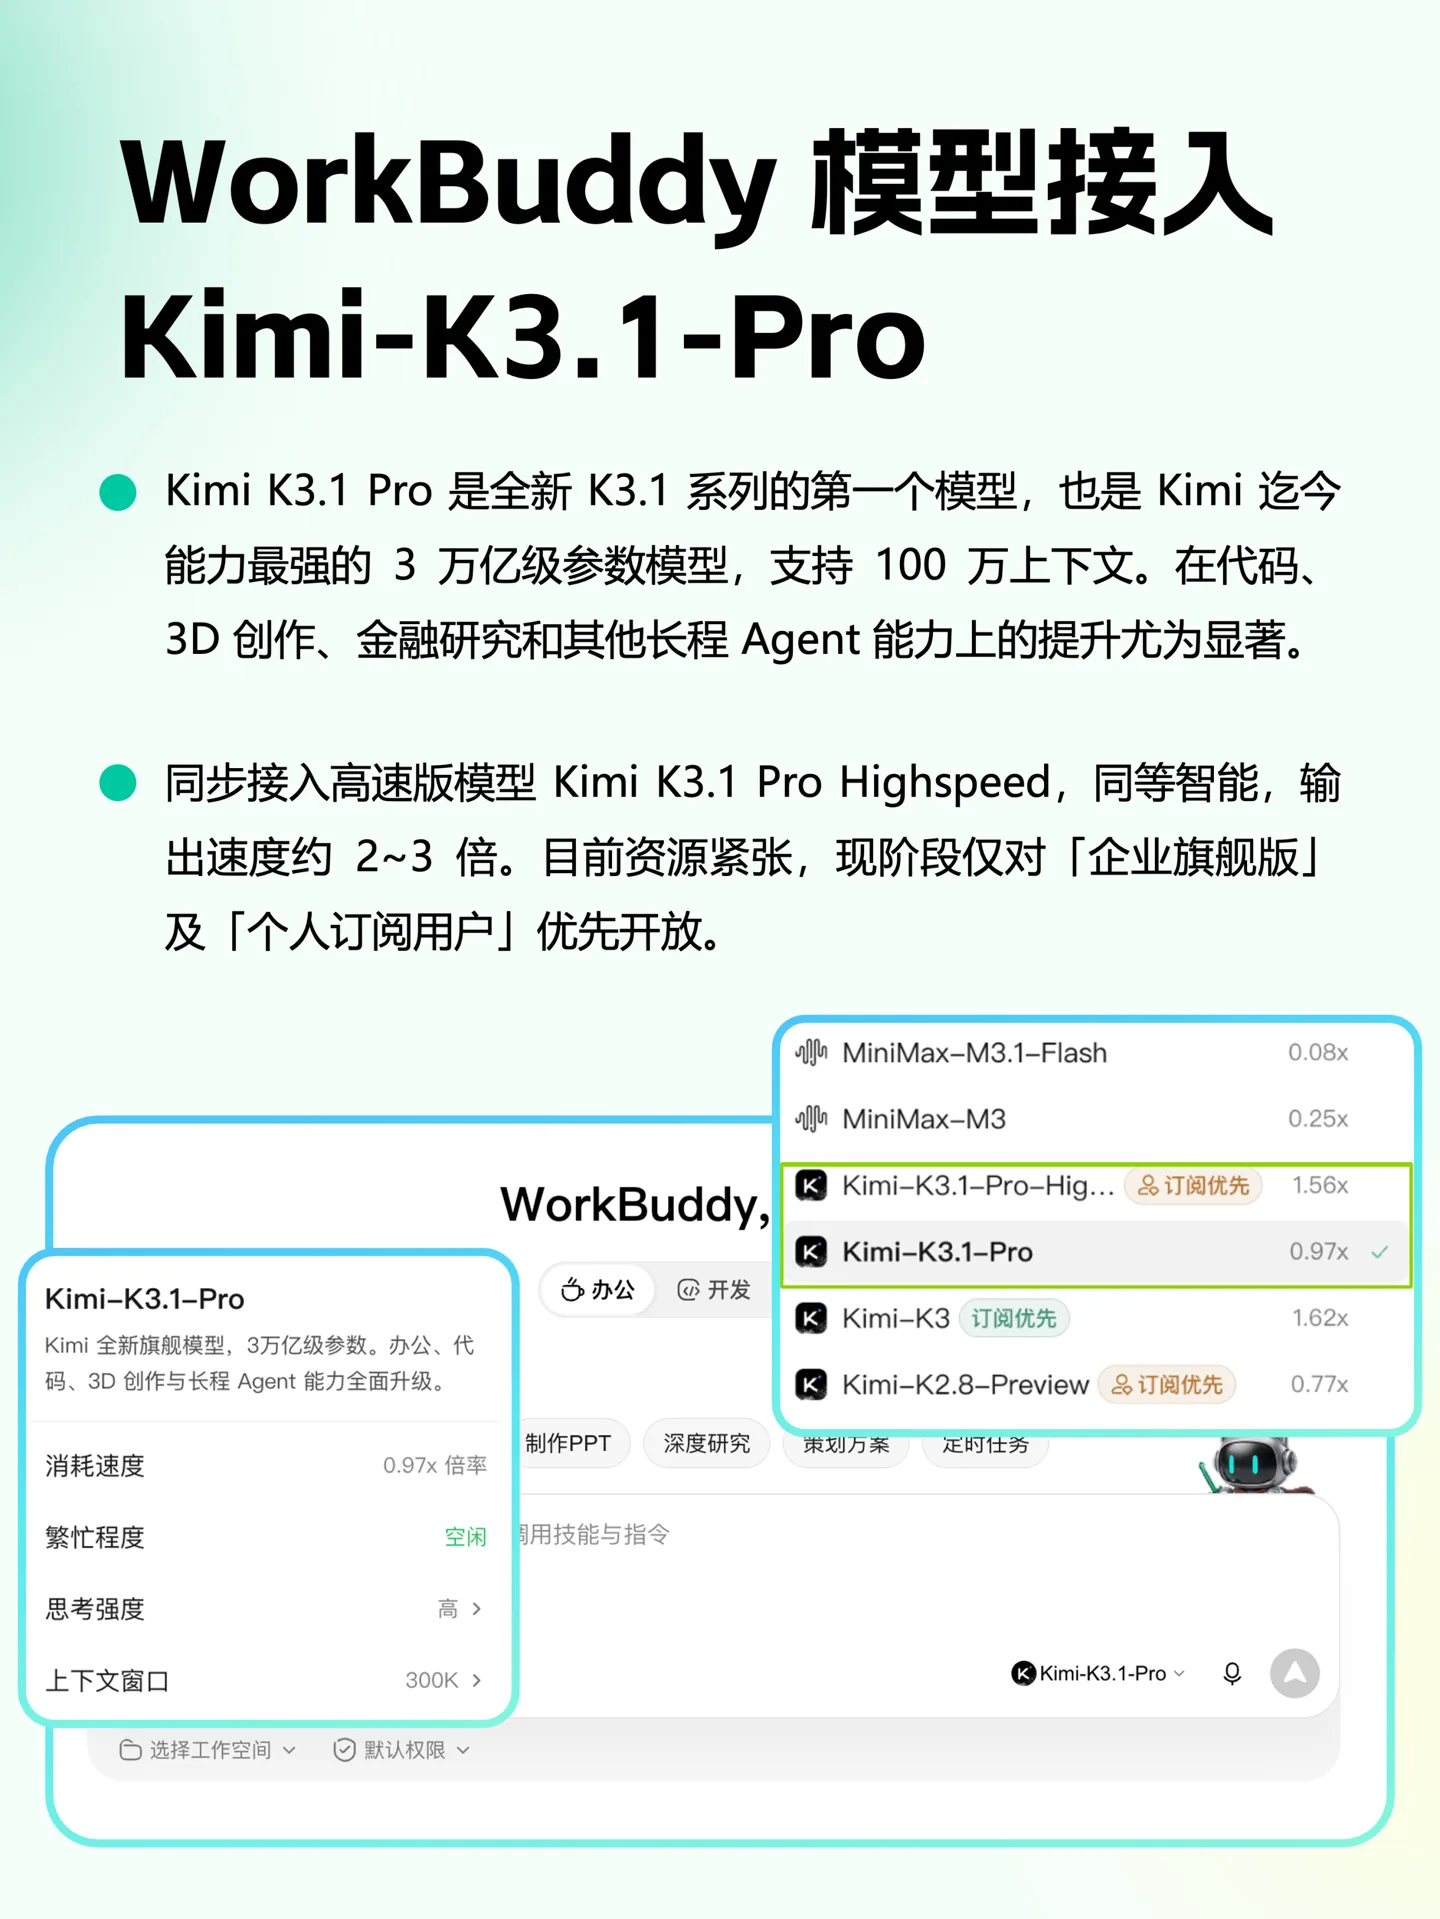
The model description follows the wording from the launch. This page does not attach a measurement made by WorkBuddy. It calls Kimi K3.1 Pro the first model in the new K3.1 series, and Kimi's most capable 3-trillion-parameter model so far, with a context of one million tokens. The gains are placed in code, 3D creation, financial research, and other long-horizon agent work. Calling it the most capable so far repeats a company line on the page. It is not a separate ranking.
[1]The page says that on code, agent, and knowledge benchmarks, K3.1 Pro reaches or approaches the level of the strongest closed models. That sentence has no comparison table. The figures printed afterward are the ones that can be checked. Those benchmark figures are also carried on this page. The page attaches no raw records, and it does not say the tasks were run inside WorkBuddy. Terminal-Bench 4.0 tests coding agents with resource-constrained terminal tasks in a real environment, and each task has a dedicated check. K3.1 Pro scores 65.7 percent, ahead of GPT-6 Astra at 58.2 percent, with a small gap to Claude Opus 5.5 at 66.4 percent. BenchCAD, as written here, rebuilds a 3D model from multi-view renderings with the help of tools. K3.1 Pro scores 92.7 percent, close to Claude Opus 5.5 at 96.2 percent and GPT-6 Astra at 95.9 percent.
[1]On the external benchmarks, OfficeQA Pro v2 is 64.4 and SpreadsheetBench v2 is 36.3. This page says both are the best current results. The page also says the model can deliver a complete financial workflow from end to end. What can be matched are these two scores, not a business record inside WorkBuddy. The research description says spending on compute in the reinforcement-learning stage rose sharply. The page gives no quantity. Priority access names the enterprise flagship plan and personal subscribers. The page does not say when other users can turn the model on, and it does not give usage inside WorkBuddy.
[1]